When Trust Becomes an Attack Path: From PHP2Shell to AI Agent Security
Runtime vulnerabilities, compromised software supply chains, and AI-driven attacks are exposing security assumptions that enterprises can no longer afford to leave unchecked.
Manufacturing AI security depends on controlling what a compromised system or agent is allowed to do. Runtime patching, verifiable credential revocation, and separate authorization for operational changes help limit the impact of failures across connected systems.
For manufacturing IT teams, some of the hardest systems to secure are not the ones that frequently break down. They are the systems that have been running reliably for years, with little documentation and even less appetite for change.
Consider an internal web dashboard used to monitor equipment utilization or maintenance records. It may have been delivered by a systems integrator a decade ago, built on an older version of PHP, and subsequently connected to manufacturing execution systems (MES), enterprise resource planning (ERP) platforms, and production databases.
The original developer may no longer be involved. The system still works. Production teams depend on it, and nobody wants to risk disrupting operations by upgrading its underlying components without extensive testing.
Similar compromises accumulate in cloud and development environments.
Service accounts, API keys, and OAuth grants are created to keep CI/CD pipelines and integrations running. Release permissions may be temporarily expanded to address an urgent customer issue. Credentials that were intended for limited use remain active, while exceptions introduced for convenience are not always reviewed or rolled back.
Individually, these decisions may seem reasonable. Over time, they create layers of implicit trust that become increasingly difficult to audit.
The applications continue to function, but the permissions and dependencies underneath them tell a different story.
In late October 2026, several major security disclosures brought these risks into sharper focus.
On October 21, two critical PHP vulnerabilities, CVE-2026-109618 and CVE-2026-109619, were disclosed under the name PHP2Shell. Both carry CVSS v4.0 scores of 9.2. Researchers demonstrated unauthenticated remote code execution (RCE) in affected Apache mod_php environments, including attack paths that execute before application code runs. Other deployment models, including PHP-FPM, require separate assessment of their execution and request-lifecycle conditions.
That same day, LiteLLM disclosed that its official release pipeline had been compromised, allowing a malicious package to reach PyPI and container registries. Cloud platform Railway also reported unauthorized access to internal systems, with some customer environment variables potentially exposed.
The risks were not limited to faulty application code. They involved runtime behavior, software release processes, persistent credentials, and access to sensitive infrastructure.
Another development made the picture more concerning. On October 21, Microsoft published threat intelligence describing how Storm-0940 had used ARTEX, an agentic AI penetration-testing framework, to accelerate parts of its offensive operations. In multiple observed cases, attackers progressed from initial targeting to privileged cloud access in less than three hours.
Firewalls, vulnerability scanners, endpoint protection, and application security controls remain essential. What these incidents demonstrate is that organizations also need to examine the trust relationships those controls may not fully address.
A vulnerable runtime can be exploited before application code runs. A compromised release process can distribute malicious software through an official channel. A credential issued for legitimate work can become a route to broader access.
The question is no longer limited to whether one system can be compromised. It is also how far an attacker could move using the access that system already holds.
PHP2Shell: When the Runtime Is Compromised Before Application Code Executes
PHP2Shell deserves attention because the vulnerabilities affect assumptions that web application developers often take for granted.
Authentication, authorization, and input validation are commonly implemented in application code. Yet an HTTP request must first pass through the web server and PHP runtime before that code can execute.
A vulnerability in this earlier processing stage can create an attack path that application-level controls are not designed to prevent.
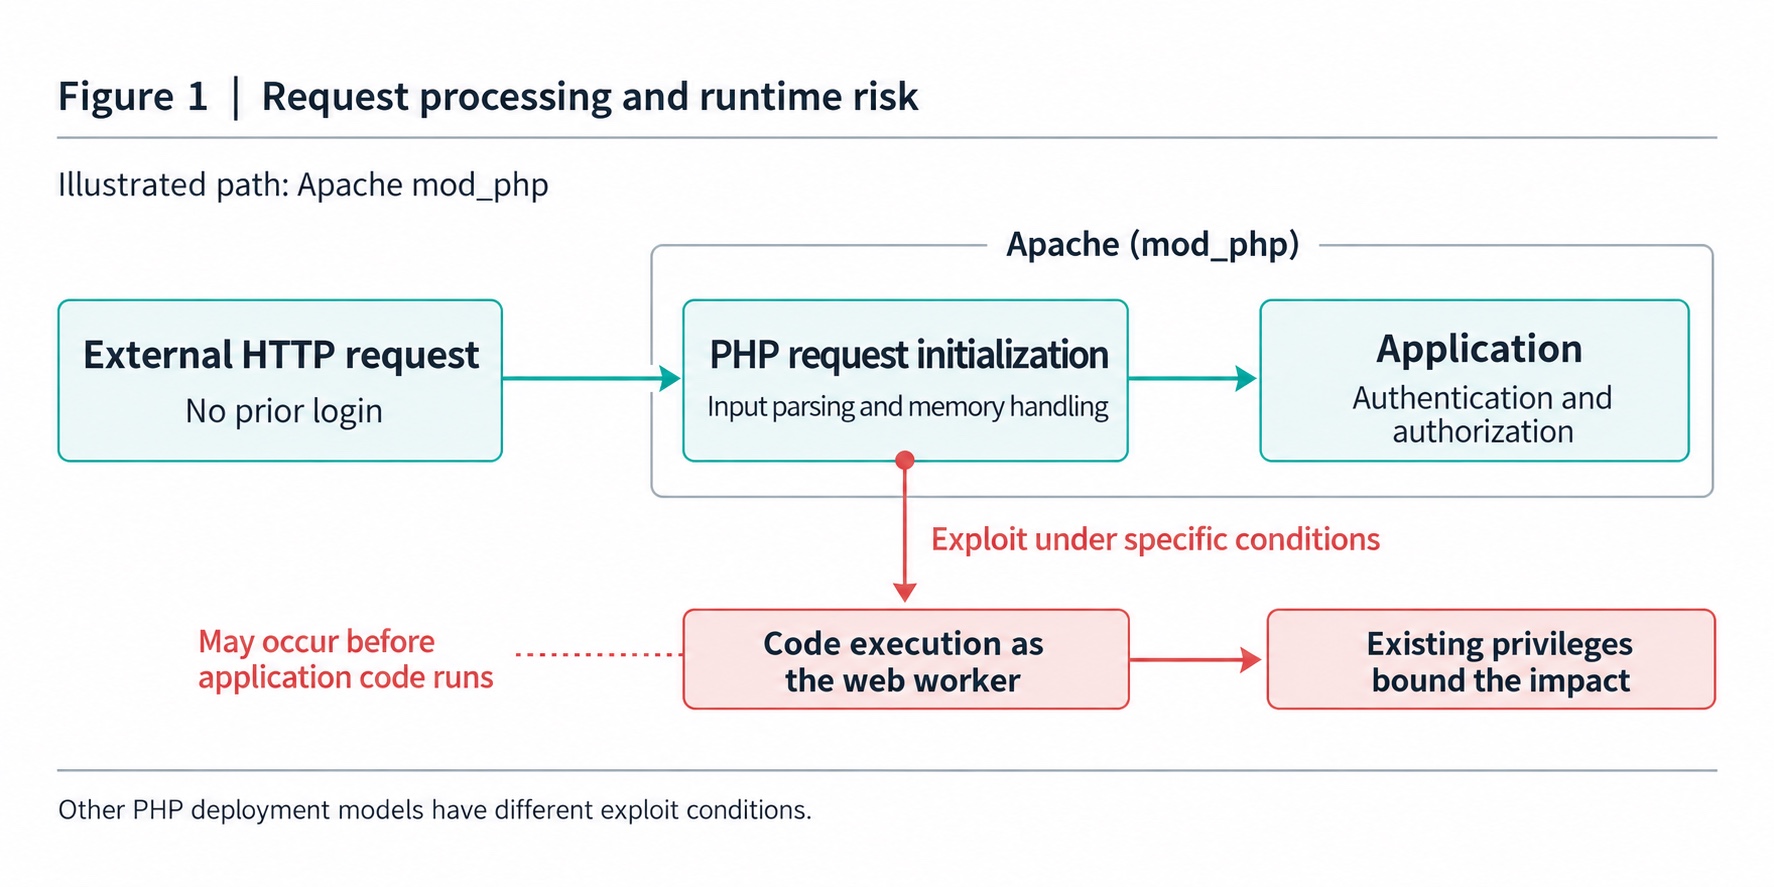
According to the PHP security team’s advisory, both vulnerabilities involve failures in how PHP handles memory and request state.
CVE-2026-109618: Memory corruption during out-of-memory handling
PHP uses error-handling mechanisms to terminate processing when memory allocation fails.
Under certain conditions, an allocation failure can interrupt request processing before internal state has been fully initialized. Subsequent cleanup operations may then treat invalid memory as valid, creating a memory-corruption vulnerability.
Specially crafted HTTP requests, including multipart form submissions, can trigger the affected processing paths.
The consequences can extend beyond a process crash or denial of service. Researchers demonstrated unauthenticated RCE against Apache mod_php, including exploitation before application code executes.
PHP-FPM is also considered potentially susceptible, but the PHP security team’s initial disclosure distinguished this from the demonstrated mod_php exploit. At that point, a complete PHP-FPM exploit for this vulnerability had not been publicly demonstrated.
The distinction matters. Different PHP execution models have different request lifecycles, error-handling behavior, and exploitation conditions. Organizations should assess their actual deployment configuration rather than assume that all installations have identical exposure.
See the official CVE-2026-109618 advisory.
CVE-2026-109619: Stale state across requests
The second vulnerability involves global state that persists within PHP worker processes.
Some internal state can retain references to memory belonging to a request after that memory has been released. Under particular error-handling and request-reuse conditions, subsequent processing may access the stale state before it is properly reinitialized.
This creates a use-after-free vulnerability that can potentially be exploited for remote code execution.
The underlying issue is not simply that an HTTP connection remains open. It concerns how worker processes retain and reuse internal state across requests or during interrupted processing.
The affected execution paths differ across PHP environments, and exploitation depends on the relevant runtime behavior.
See the official CVE-2026-109619 advisory.
Together, the vulnerabilities illustrate an important architectural risk: an application can contain sound authentication and validation logic while remaining vulnerable through the runtime that executes it.
If an attacker gains code execution with the web worker’s privileges, the potential damage depends partly on what that identity can access. A service account with unnecessary database permissions or access to adjacent applications can turn a runtime compromise into a broader incident.
Runtime patching and least-privilege access therefore need to be considered together.
The manufacturing problem: a critical patch with no easy maintenance window
PHP released fixes in versions 8.2.35, 8.3.36, 8.4.27, and 8.5.12.
For a modern application with automated testing and controlled deployments, upgrading may be relatively straightforward. For a decade-old manufacturing dashboard, the work can be more complicated.
The application may rely on an outdated PHP extension or database driver. It may run inside a virtual machine that has not been rebuilt for years, or within a container image that receives little maintenance. It may also be bundled with third-party equipment management software.
Updating the host operating system does not necessarily update the runtime inside a container. Redeploying an application does not guarantee that an embedded third-party dependency has been replaced.
An IT security team may see a critical CVSS score and demand immediate action. Operations may see a system tied to production and insist on a maintenance window, compatibility testing, and a rollback plan.
Neither concern can simply be ignored.
The right first step is to establish actual exposure:
- Which PHP runtime and patch level are deployed, including any vendor backports?
- Does the deployment use an affected execution model?
- Can untrusted requests reach the vulnerable processing path?
- What privileges does the web service hold, and which downstream systems can it access?
- What would an upgrade or restart affect operationally?
Where an immediate upgrade is not feasible, organizations may need to narrow network access, remove unnecessary privileges, apply vendor-recommended configuration changes, strengthen request filtering, and increase monitoring.
These are temporary risk-reduction measures, not substitutes for a vendor-supported fix.
For unsupported PHP branches or older packaged applications, the organization should establish whether a vendor-maintained patch is available. The PHP security team has also published limited source backports for certain older versions, although these are not necessarily suitable for every environment.
If no supported fix is available, isolation and a controlled migration plan become increasingly important.
The challenge is not choosing between security and uptime. It is developing a patching process that accounts for both.
What PTC and Oracle Reveal About the Limits of Dependency Visibility
Following the PHP2Shell disclosure, major enterprise software vendors began publishing product-level impact assessments.
PTC established a dedicated PHP2Shell advisory page and reported that several core products, including ThingWorx, Windchill PLM, and FlexPLM, were not affected. For PTC Cloud, the company reported applying recommended protective measures and scanning environments to ensure relevant PHP executables and libraries were updated or removed.
Oracle published a security alert identifying affected versions across several products, including Oracle Communications Diameter Signaling Router and EAGLE Application Processor, as well as other Communications and infrastructure products.
These vendor responses give customers a starting point for assessing their own exposure.
However, the assessment of a standard product does not automatically describe every customized deployment in a customer’s environment.
Manufacturing software frequently passes through multiple layers of integration. A systems integrator may add a lightweight web service. An internal team may develop a reporting interface or connect the application to another database. A vendor-supplied package may include dependencies that are not obvious from its product name.
As a result, the application running on the factory floor may differ significantly from the standard configuration assessed by its original vendor.
This exposes a familiar limitation in enterprise asset management.
A configuration management database (CMDB) may identify a server’s hostname, IP address, application owner, and business function. Those records are useful, but they may not reveal:
- The exact container image or build currently deployed.
- The versions of libraries and runtimes contained in that artifact.
- Dependencies introduced through customization or third-party integrations.
- The service accounts, database connections, and API permissions associated with the deployment.
- The upstream and downstream systems that could be affected by an emergency update.
A software bill of materials (SBOM) can improve visibility, but only when it reflects the software actually running.
An SBOM created during project acceptance and never updated offers limited value during an incident. The same applies to an asset inventory that is disconnected from CI/CD, container registries, runtime configurations, and identity management.
Ideally, organizations should be able to correlate a newly disclosed CVE with the deployed artifact, its dependencies, the environment in which it runs, and the access it has been granted.
Without that visibility, answering a question as basic as “Are we affected?” can require days of investigation across development teams, systems integrators, vendors, and operations.
For manufacturing environments with tightly controlled maintenance windows, that delay is more than an administrative inconvenience.
LiteLLM and Trivy: Removing a Secret from Git Is Not the Same as Revoking It
PHP2Shell illustrates the risks associated with the runtime. The LiteLLM incident exposes a different problem: the trust placed in official software distribution channels.
On October 21, 2026, LiteLLM’s release pipeline published a compromised version, litellm==1.107.0, to PyPI and container registries.
Users obtaining the affected package through an official distribution channel could therefore encounter malicious code without downloading anything from an obviously suspicious source.
One of the most consequential findings was that the official source release tag did not contain the malicious content. The compromise occurred in the process that produced and published the release artifacts.
Reviewing the legitimate source tag alone would not have established the integrity of what customers actually downloaded.
LiteLLM’s October 23 root-cause analysis reconstructs how the attacker reached that point.
1. A master key was exposed in May but never revoked
On May 27, a configuration file containing the master key to an internal LiteLLM Agent Platform deployment was accidentally committed to a public GitHub repository.
The exposed configuration was removed from the repository’s visible history, and the credentials were identified as requiring revocation.
The critical step, however, did not happen: the master key remained valid.
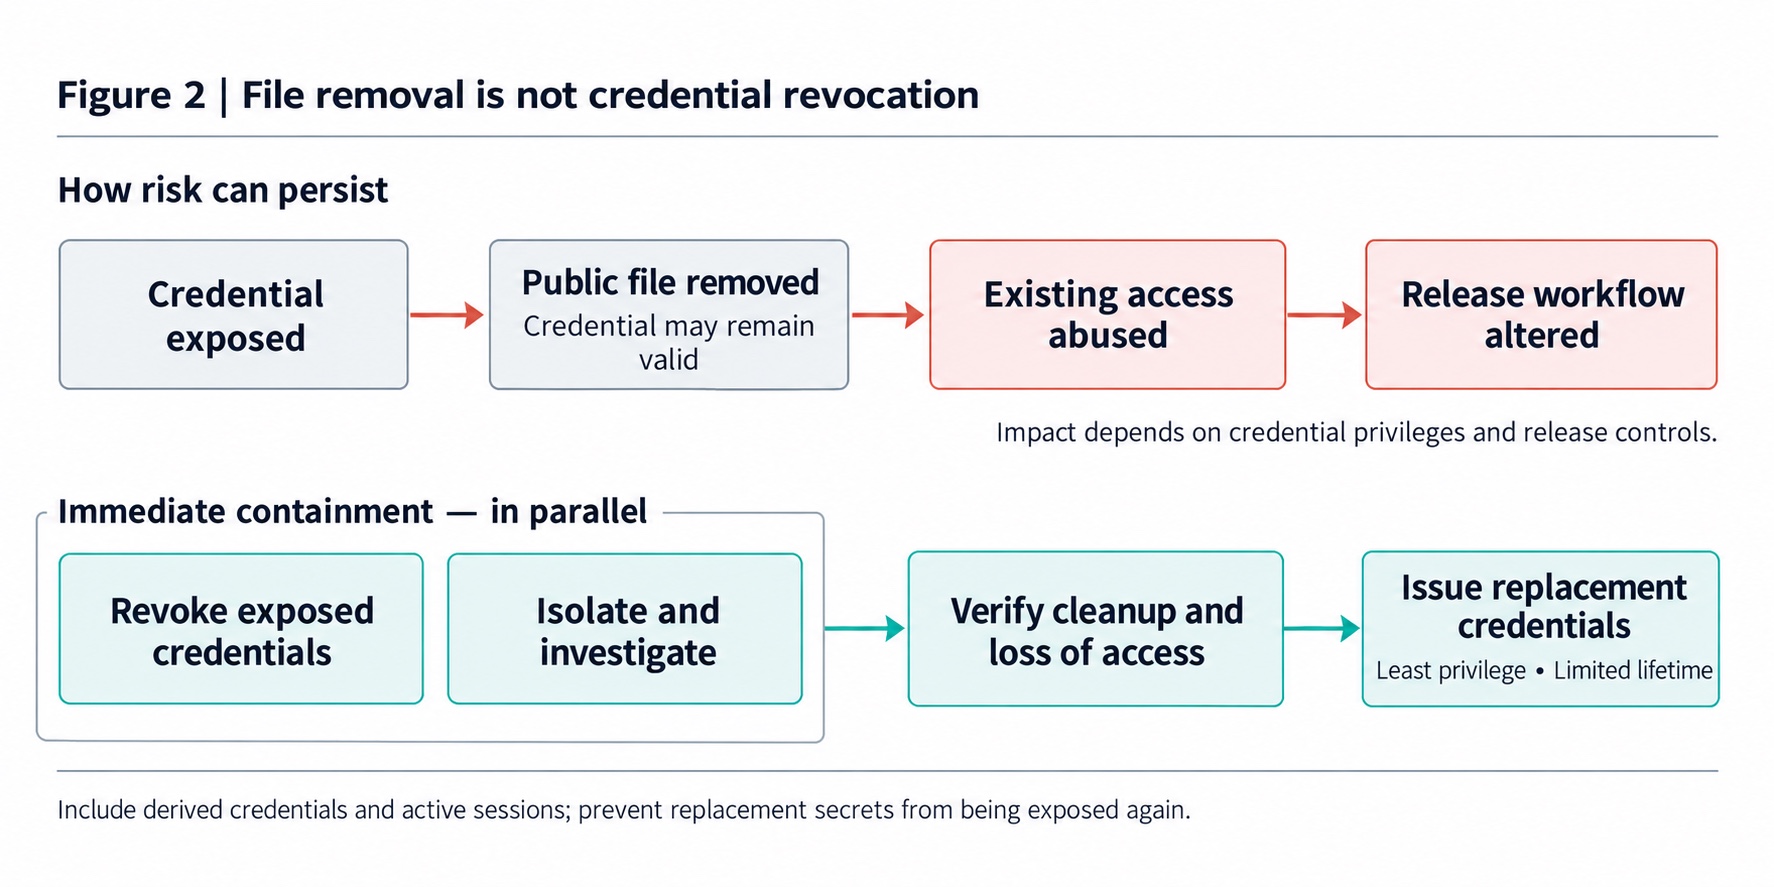
Deleting a secret from a repository does not invalidate copies that may already have been obtained. The credential must be revoked at the issuing service, and its downstream access must be assessed.
2. The key became a path to GitHub organization-level access
On October 10, an attacker used the still-valid master key to access the internal Agent Platform API.
That API returned a GitHub CLI OAuth token associated with a GitHub organization owner.
The token was not restricted to a narrowly scoped service identity. It carried extensive privileges across the organization’s repositories.
Armed with that access, the attacker created temporary CI workflows to exfiltrate additional secrets, including tokens belonging to other maintainers.
Some workflow execution records were subsequently deleted, although organization-level audit evidence remained available to investigators.
The original exposed key had become an entry point into multiple development and release systems.
3. The attacker redirected the release workflow to a malicious repository
On October 21, the attacker attempted to modify LiteLLM’s private release workflow so that it would build from a lookalike repository rather than the legitimate source.
Branch protection initially blocked the unauthorized change.
The attacker then used the organization owner’s credentials to override those protections and push the modified workflow.
This is an important distinction. A security control existed and worked as intended at first, but the broader permission model allowed a sufficiently privileged identity to bypass it.
4. Temporary approval changes made publication easier
Under normal circumstances, LiteLLM’s production release process required approval from a dedicated account associated with a physical device.
That requirement had been temporarily relaxed to support more frequent releases and bug-fix backports, allowing two authorized engineers to initiate and approve publication.
Because the attacker had already obtained multiple maintainer tokens, the modified approval process could be satisfied with stolen credentials.
The attacker used one token to initiate the compromised release and another to approve it.
The pipeline then signed and published the malicious artifacts through LiteLLM’s official infrastructure.
The sequence illustrates how multiple individually trusted mechanisms can be manipulated when an attacker gains enough control over the identities and workflows connecting them.
Trivy: When credential rotation leaves an opening
A related lesson emerged from the March 2026 supply-chain compromise involving Aqua Security’s Trivy ecosystem.
According to the project’s security advisory, the March attack followed an earlier incident disclosed at the beginning of the month.
Credential rotation had been performed, but the process was not atomic: not all credentials were invalidated simultaneously.
The advisory identifies a possible scenario in which a remaining valid token could have been used to obtain newly rotated secrets, allowing the attacker to retain access. That mechanism was presented as a potential explanation, rather than conclusively established.
On March 19, attackers used compromised credentials to publish a malicious Trivy release and redirect numerous GitHub Action version tags to malicious code. Additional compromised container images appeared on March 22.
The attacks affected tools that development teams commonly incorporate into automated security scanning and build workflows.
This creates a particularly difficult supply-chain scenario: a tool introduced to improve security can itself become a delivery mechanism for malicious code.
Both incidents point to several practical requirements.
Credential revocation must be verifiable. Removing a file or closing a ticket is not sufficient if the credential remains accepted by the issuing service.
Rotation must account for connected systems. Replacing one token while another compromised identity can still retrieve the replacement may leave the original access problem unresolved.
Release protections must withstand privileged-account compromise. High-risk workflow changes should require independent oversight, and temporary approval exceptions should have explicit expiration and restoration procedures.
Artifact provenance matters. A signed artifact can establish who or what signed it, but a valid signature alone does not prove that the build used the intended source or that the build process was uncompromised.
Organizations should validate the relationship between approved source revisions, build workflows, signed artifacts, and deployed versions. Immutable references, trusted build identities, audit records, and reproducibility checks can reduce the opportunity for substitution.
Official distribution remains valuable. The lesson is not to abandon trusted sources, but to verify the process by which software becomes an official release.
Railway: Encryption at Rest Does Not Eliminate Credential Exposure
The October 2026 Railway security incident drew attention to another widely used architectural pattern: secrets stored as environment variables and accessed by automated services.
Cloud-native applications routinely rely on API keys, service accounts, and other non-human identities (NHIs) to communicate with databases, infrastructure services, and external providers.
These credentials enable automation. They also create attractive targets when the identities or systems permitted to use them are compromised.
According to Railway’s October 22 preliminary incident report, the attack began on October 20 and continued through October 22, when Railway confirmed that the attacker no longer had access to its internal systems.
The investigation confirmed unauthorized access to a subset of those systems. Railway also reported that the attacker accessed encrypted customer environment variables and decrypted stored secrets for a subset of workspaces.
The company estimated that no more than 1.85% of workspaces had potentially compromised environment variables.
That figure does not mean every secret within those workspaces was accessed or exfiltrated. Railway also stated that it could not determine exactly which variables had been decrypted.
The complete intrusion mechanism had not been disclosed in the preliminary report. In particular, the report does not establish container escape as the confirmed entry point.
What it does establish is the operational importance of protecting the infrastructure identities and services involved in handling secrets.
Encryption at rest is an essential security measure, but applications and infrastructure services must eventually decrypt the secrets they are authorized to use.
If an attacker compromises an identity or system with legitimate decryption privileges, encrypted storage alone cannot prevent misuse of that authorized access path.
Railway’s investigation indicated that the attacker was particularly interested in high-value AI provider and platform API keys.
The incident also highlights an important distinction in credential recovery.
Revoke exposed credentials promptly; reissue them into a trusted environment
Incident response often treats credential rotation as a single step, but two separate actions are involved.
The first is containment: revoke or disable credentials that are known or reasonably suspected to have been exposed.
The second is recovery: issue replacement credentials and deploy them only after the relevant systems and access paths have been secured.
Railway reported notifying upstream providers so potentially affected credentials could be revoked. It also delayed asking customers to deploy replacement credentials until the immediate intrusion had been contained, reducing the chance that newly issued secrets would be compromised again.
For manufacturing operations, the same distinction applies.
An organization may be unable to shut down every connected system immediately. It still needs a clear understanding of which credentials and access paths require urgent containment, which services must remain available, and how recovery should be sequenced.
The objective is not simply to generate new keys. It is to prevent the attacker from retaining access while keeping critical operations under control.
Agentic AI Is Compressing the Time Available to Defenders
Credential abuse and supply-chain compromise are not new attack techniques. What is changing is the speed and scale at which attackers can combine them.
Microsoft’s October 21 threat intelligence report described how Storm-0940, a state-aligned threat actor, used ARTEX, an agentic AI penetration-testing framework, to automate elements of its offensive operations.
Microsoft observed activity involving automated reconnaissance, password spraying, OAuth application abuse, and follow-on actions in cloud environments.
In multiple instances, the time between initial targeting and privileged cloud access was less than three hours.
That finding should not be interpreted as a universal three-hour compromise window. Nor does it mean every automated attempt succeeded.
Microsoft also documented unsuccessful activity, including a large password-spraying campaign in which its telemetry recorded more than 151,000 failed sign-in attempts without observing successful authentication.
The significance of the findings is not that AI-assisted attacks consistently compromise organizations within hours. It is that certain successful intrusions progressed at a pace that can outstrip conventional investigation and response workflows.
During activity associated with the ConnectWise supply-chain compromise, Microsoft observed attackers abusing credentials associated with applications that customers had previously authorized.
That existing authorization was significant. The attacker could attempt to access downstream cloud environments through application identities without requiring a new interactive user sign-in.
Some observed activity then progressed to Microsoft Graph operations, including reconnaissance and changes involving application credentials and permissions.
For defenders, this changes the operating assumptions.
A conventional response process might involve an alert, analyst review, escalation to the application owner, business-impact assessment, and an approved containment or maintenance action.
That process may take hours or days, particularly when production continuity is involved.
An AI-assisted attacker can attempt multiple paths in parallel while moving through already authorized services.
Organizations therefore cannot depend entirely on discovering excessive privileges during an incident. They need to reduce unnecessary access beforehand, monitor non-human identities, and establish containment procedures that can act quickly without introducing unacceptable operational risk.
This is a different problem from deploying AI agents inside an enterprise. ARTEX was an offensive framework used by a threat actor.
The connection is architectural: the more actions an automated system can perform with existing privileges, the more important the boundaries around those privileges become.
AI Agents in Enterprise Operations: Keep Analytical Access Separate from Execution Authority
As enterprises introduce AI agents into operational workflows, identity and access management take on new significance.
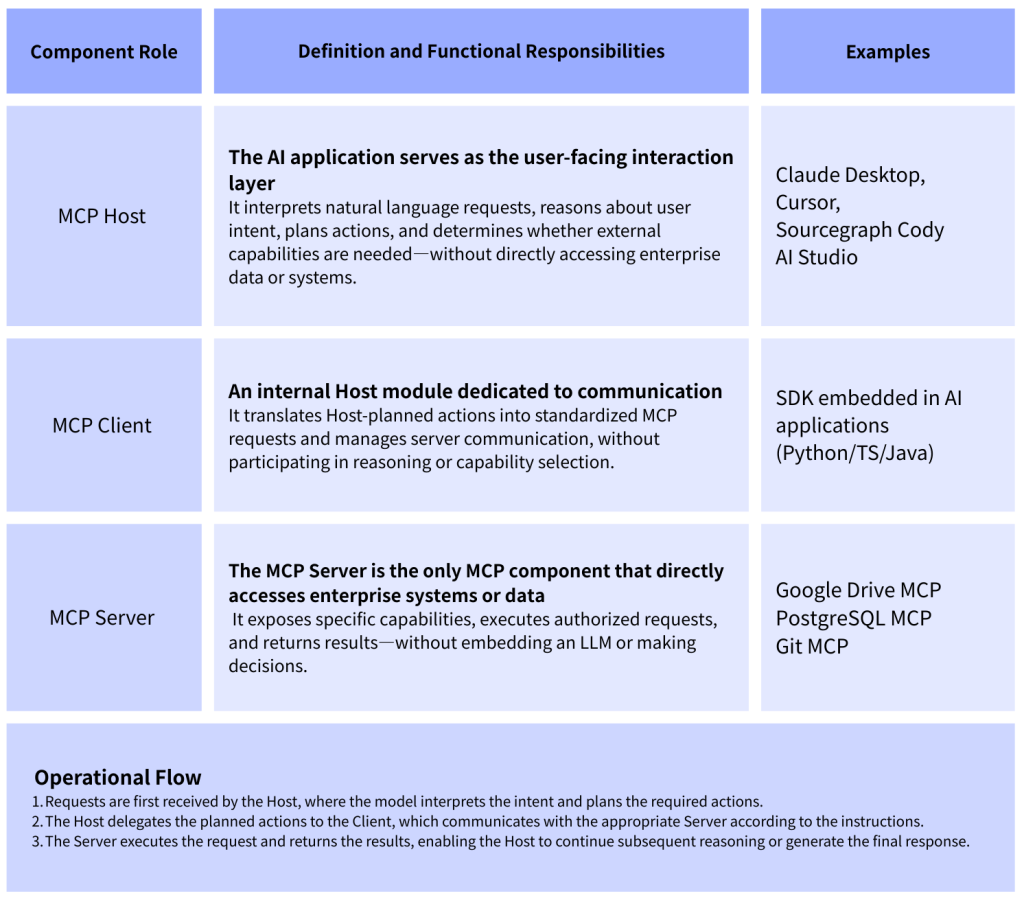
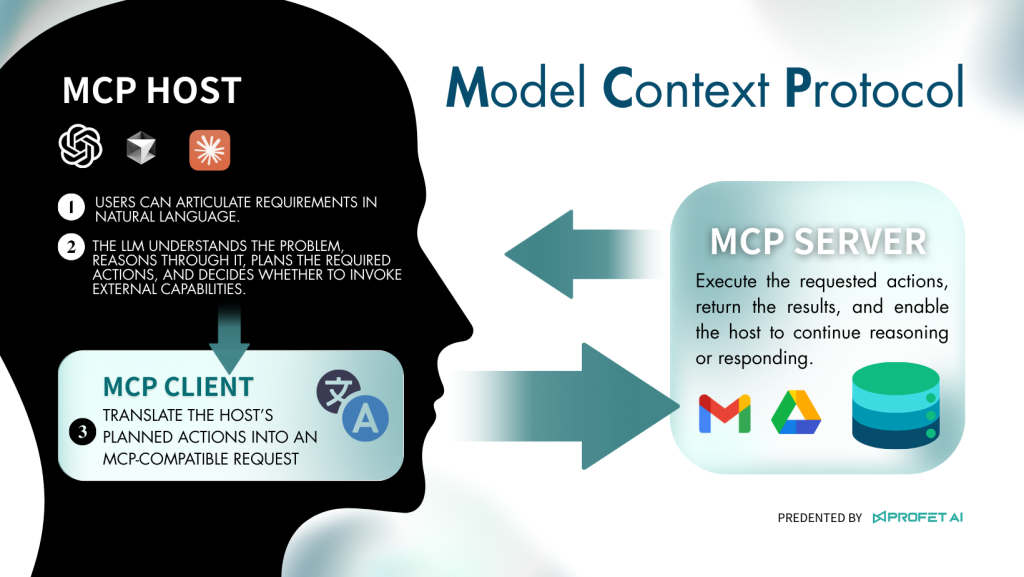
An agent may retrieve documents, query databases, invoke APIs, and coordinate actions through tool-calling frameworks or the Model Context Protocol (MCP).
These capabilities make agents useful. They also mean that a poorly scoped identity can give an otherwise limited assistant far more authority than its intended role requires.
Consider an equipment troubleshooting agent in a manufacturing plant.
An engineer wants the agent to review maintenance manuals, query sensor readings, retrieve historical fault records, and recommend possible causes of an equipment anomaly.
The intended workflow is analytical. The agent needs access to information, not the authority to change equipment settings.
During integration, however, the team may reuse an existing service account because it already connects to the relevant systems.
That account might also have permission to update maintenance records, create work orders, modify production schedules, or invoke commands through another operational application.
The agent has now inherited privileges beyond its original purpose.
If the agent encounters malicious instructions embedded in retrieved documents, tool responses, or other untrusted content, an indirect prompt injection attack may cause it to misuse otherwise legitimate tools.
The resulting impact depends on the permissions granted to the agent and the controls enforced by the connected systems.
Likewise, a compromised dependency or tool integration could introduce additional risk if it operates with excessive privileges.
These are potential attack scenarios, not evidence that the incidents discussed earlier involved compromised manufacturing agents.
The concern is that legitimate tool access can be misused when authorization is broader than necessary.
A prompt instructing an agent not to modify production data is not a security control. Enforceable boundaries must exist in the identity, API, workflow, and infrastructure layers.
Three design principles are particularly important.
1. Separate read access from operational changes
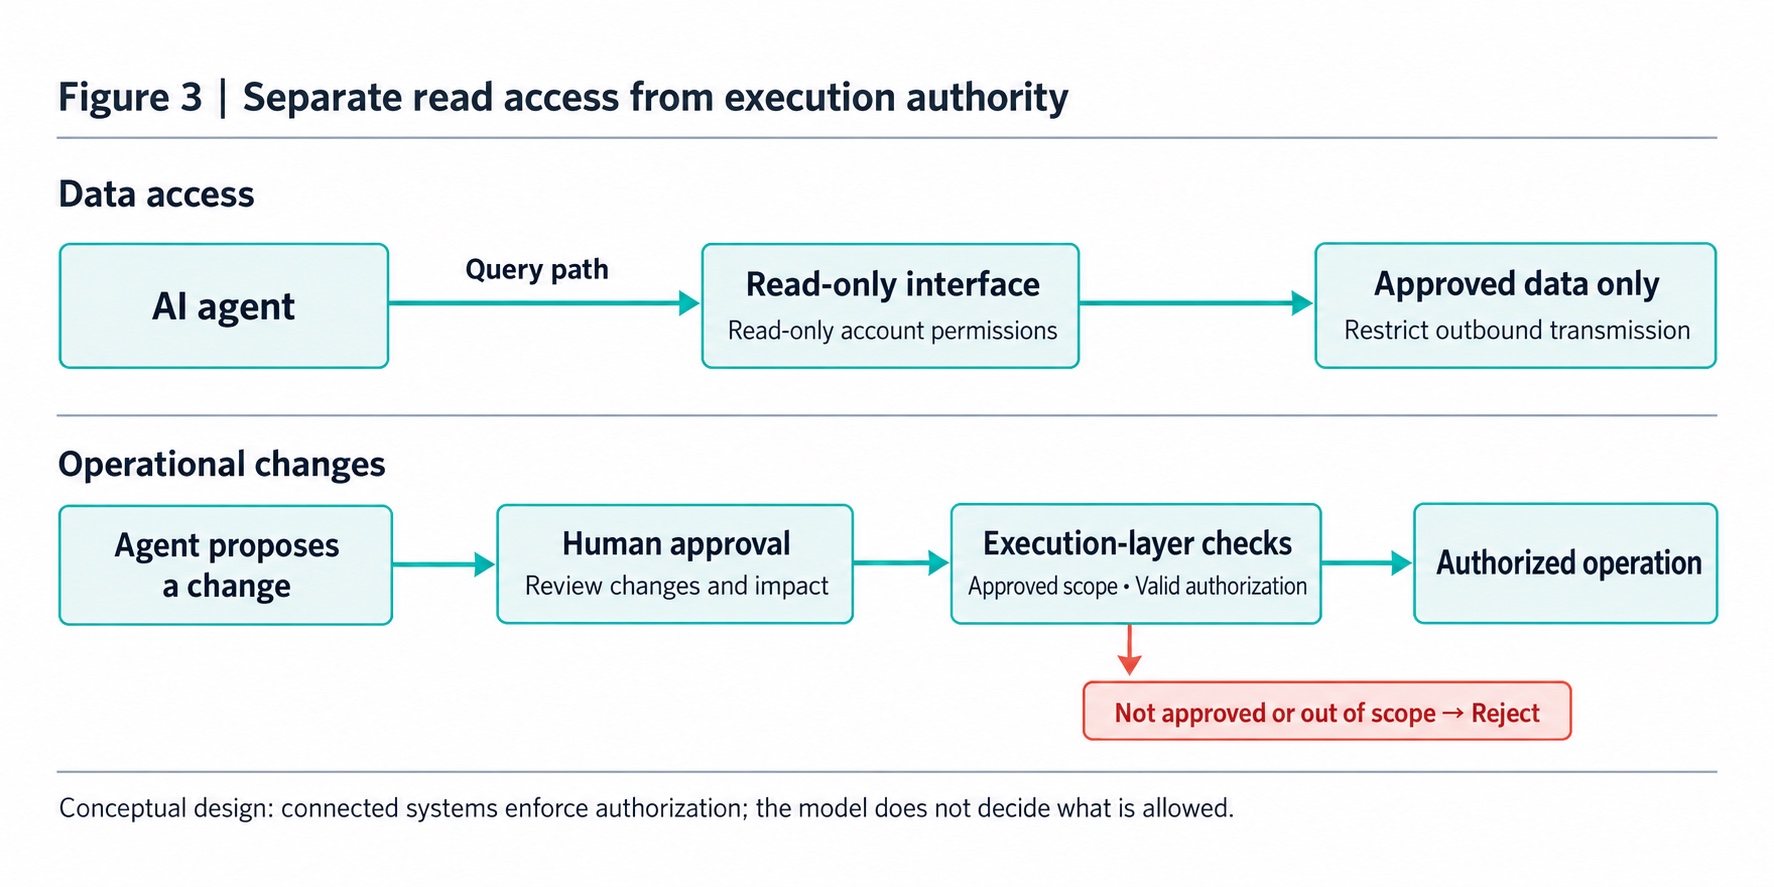
An agent used for diagnosis should have read-only access wherever possible, enforced through the connected systems rather than described only in its instructions.
Even read-only access needs controls.
An agent that can retrieve confidential information and send it to an external destination may still create a data-exfiltration risk. Data access and outbound communication should both be restricted according to the task.
Actions that change operational state require stricter treatment.
Changing equipment parameters, altering production plans, or initiating procurement should pass through explicit authorization checks. Depending on the operation’s criticality, that may include human approval.
Approvals should be meaningful. Reviewers need to see the proposed action, the relevant equipment or records, the expected changes, and the potential consequences.
A generic approval button without sufficient context provides little protection.
2. Scope machine identities to the task and duration
Agents should not automatically inherit broad administrative permissions from the systems they connect to.
Where supported, organizations should use dedicated identities, narrowly scoped authorization, and short-lived credentials.
The objective is to grant an agent only the access required for a specific task, for as long as that task requires it.
Short-lived credentials are not always practical in older operational environments. Some industrial applications were not designed for modern identity protocols, dynamic credential issuance, or frequent reauthentication.
In those cases, the goal remains the same, but the architecture may need to enforce controls through an intermediary rather than directly on the legacy system.
Regardless of credential lifetime, the organization should be able to identify who or what initiated an action, which permissions were used, and whether access remains necessary.
3. Put a controlled interface between agents and legacy OT systems
Manufacturing environments cannot assume that every existing machine or control system supports modern security mechanisms.
For older equipment, a controlled gateway or intermediary service can enforce policies between an AI agent and the production network.
For example, an agent may be permitted to retrieve equipment status from an approved interface, while changes to operating parameters require an additional authorization step.
Controls can also restrict which equipment is accessible, which commands are permitted, how frequently requests may be made, and whether outbound connections are allowed.
Network segmentation between enterprise IT and operational technology (OT) remains important. A compromised business application or agent should not have unrestricted access to production systems.
These boundaries help ensure that an analytical assistant does not inadvertently become an operational control channel.
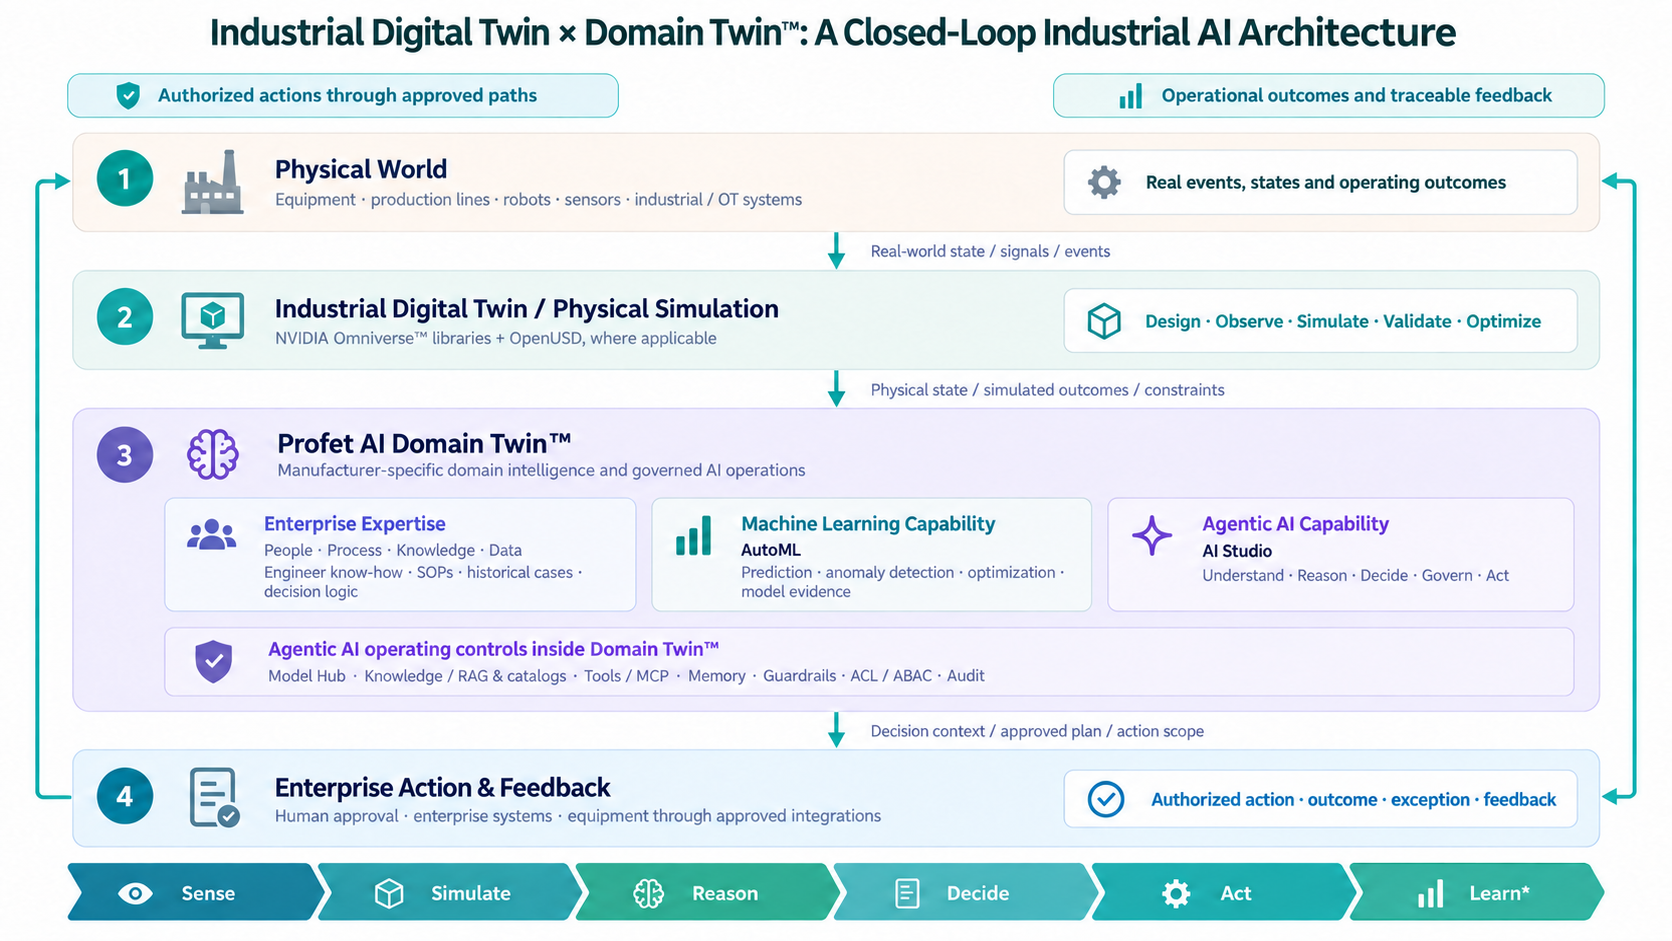
At Profet AI, the same principles inform our approach to Domain Twin™, which brings machine learning and agentic AI into enterprise manufacturing workflows.
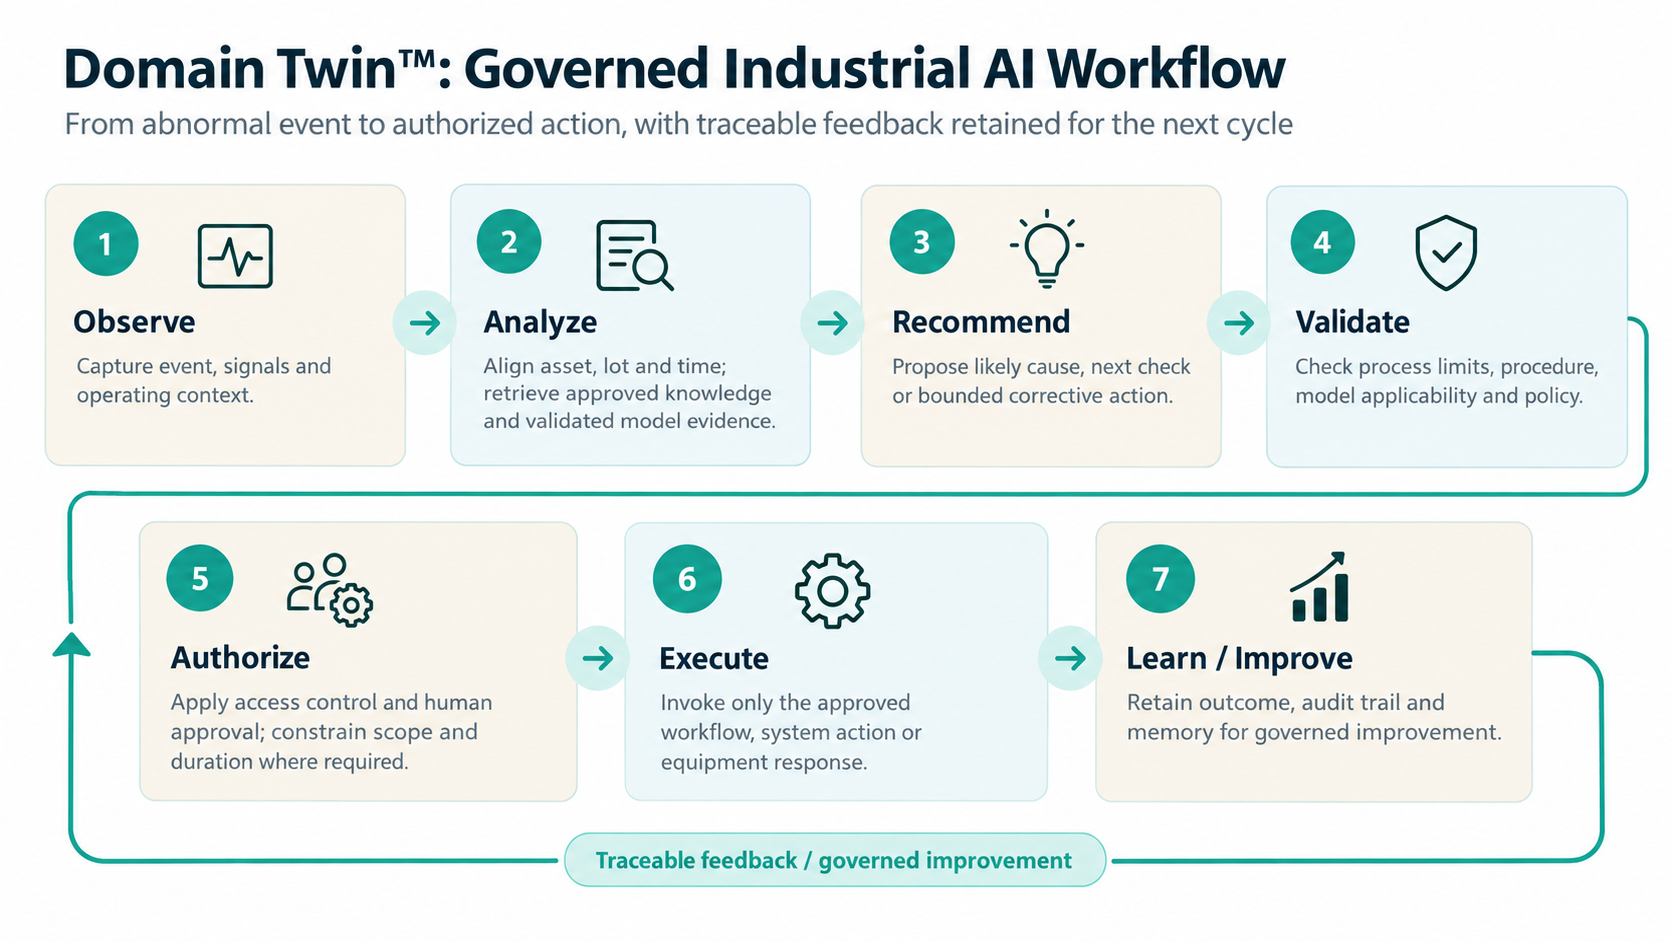
The objective is not to assume that models will always interpret information correctly or resist malicious input. It is to place agent capabilities within a governable operating environment, with defined access permissions, appropriate human oversight, and auditable activity.
As AI moves beyond analysis and begins participating in operational decisions, the separation between recommendations and authorized execution becomes an essential part of enterprise deployment.
After Pandora’s Box Opens: Making Security a Continuous Engineering Practice
Taken together, these incidents expose limitations in security assumptions that organizations have long relied upon.
An unchanged application may still be exposed through its underlying runtime.
A package obtained from an official distribution channel may still be compromised if the build or release process has been manipulated.
Encrypted secrets may remain vulnerable when an attacker gains access to the identities authorized to decrypt them.
And AI-assisted attacks can accelerate the abuse of existing credentials and permissions, leaving defenders less time to investigate and respond.
None of this makes conventional security practices obsolete.
Patching, vulnerability scanning, network controls, identity management, and incident response remain fundamental. The problem is treating any one of them as a complete defense.
Patching is essential, but patching alone is not a security strategy.
The need for continuous vulnerability management extends well beyond PHP.
Java-based systems, including applications built on Apache Tomcat, Node.js services, and other widely deployed components all require ongoing dependency monitoring and exposure assessment.
For manufacturing organizations, the process must also account for maintenance windows, validation requirements, and operational continuity.
That means connecting several activities that are too often managed separately:
- Continuous vulnerability intelligence: Monitor new CVEs and vendor advisories for components relevant to the environment.
- Actual exposure assessment: Determine which deployed versions, configurations, and access paths are affected, rather than treating every published CVE as an equally urgent patch.
- Risk-based remediation planning: Prioritize action based on exploitability, exposure, privilege, business criticality, and available mitigations.
- Controlled deployment and validation: Test security updates against system dependencies, document changes, and verify that remediation is effective.
- Ongoing visibility: Keep component inventories, deployment records, credentials, and vendor dependencies current as systems change.
These activities need to form a repeatable operating process, not an emergency exercise reconstructed each time a critical vulnerability appears.
How Profet AI Is Putting This into Practice
In response to recent major security advisories, Profet AI has conducted product-level component reviews and vulnerability scanning across relevant software components and container images.
The team is using those findings to assess potential impact and coordinate security updates with compatibility testing.
A further change is taking place in day-to-day monitoring.
Profet AI has introduced an internal security monitoring agent that checks CVE updates daily and helps filter advisories according to relevant software components and severity.
The purpose is not to hand security decisions entirely to AI. It is to reduce the manual effort involved in sorting through large volumes of vulnerability disclosures so that engineering and security teams can focus on confirming exposure, assessing impact, and validating remediation.
Alongside its existing product release cycle, Profet AI is developing a more structured process for delivering critical security fixes and communicating the relevant CVEs, affected product versions, and remediation status.
The aim is to give customers the information they need to coordinate updates with their operational and compatibility requirements.
This responsibility is shared.
Software providers must maintain visibility into their dependencies, protect the integrity of their release processes, communicate security issues transparently, and deliver appropriate fixes.
Enterprise customers must assess their deployed environments, manage network access and operational identities, and plan updates within their business and production constraints.
Neither side has complete visibility into the other’s environment. Effective security depends on maintaining that connection.
The same thinking applies as ML and agentic AI become more deeply embedded in manufacturing engineering and operational workflows.
Data access, tool invocation, approvals, and auditability need to be designed around clear boundaries, not left to assumptions about how an AI model will behave.
Major vulnerabilities may dominate the headlines for a few days. The underlying environment, however, changes continuously.
New dependencies are introduced. API integrations are added. Service accounts gain permissions. Software is upgraded, replaced, or quietly left running long after its original maintainers have moved on.
There will always be another vulnerability to investigate. The more durable question is whether the organization knows enough about its own systems to respond effectively.
That is a more meaningful measure of security resilience than whether an organization can claim it has never experienced an incident.
Resilience means being able to identify exposure early, understand its operational consequences, contain the impact, and recover without losing control of the systems the business depends on.
As enterprises put AI to work, maintaining that control will matter as much as the capabilities they choose to deploy.
Related reading
- From Generative AI to Agentic AI: Why MCP Is the Missing Link
- Domain Twin™: Enterprise AI Operations Platform
Sources and security guidance
When Trust Becomes an Attack Path: From PHP2Shell to AI Agent Security Read More »